Thursday, 29 May 2014

Understanding Evaluation Metrices.


Confusion Matrix is a tabular layout that can be used to measure the performance of an algorithm. Each Column represents predicted value and each row represents actual value. 
Lets take an example of testing a person for cancer. 
If the person has cancer , the test will say it as positive and if not then negative.
There are can be 4 outcomes if we consider test as an experiment.

1) The patients were suffering from cancer and our test recognized them as suffering from Cancer : These are called TRUE POSITIVE.
2) The patients were suffering from cancer but tests showed negative : These are called TRUE NEGATIVE
3) Patients who were healthy but were diagnosed as suffering from Cancer : FALSE POSITIVE
4) Patients who were not suffering from cancer and test said the same : FALSE NEGATIVE.

Precision (Positive Predicted Value) : proportion of patients test showed as having cancer and they actually had cancer.
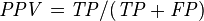
\mathit{PPV} = \mathit{TP} / (\mathit{TP} + \mathit{FP})
  
Recall(True Positive Rate)  : proportion of patients that actually had Cancer were diagnosed by test as having cancer. :
\mathit{TPR} = \mathit{TP} / P = \mathit{TP} / (\mathit{TP}+\mathit{FN})
 
Precision and Recall Inversely Related

Accuracy : 
Ratio of Correctly classified instances to total instances.
In layman terms : Number of times the test were right 
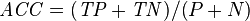
\mathit{ACC} = (\mathit{TP} + \mathit{TN}) / (P + N)

Where P and N are total number of tests.


F1 :  is a measure that combines the precision and recall rates by computing the harmonic mean between them. F-Measure does not consider True Negatives into account. 

\mathit{F1} = 2 \mathit{TP} / (2 \mathit{TP} + \mathit{FP} + \mathit{FN})


ROC Curve
Receiver Operating Curve(ROC)  is a plot to show change in performance of Binary Classifier with change in Threshold. The graphs are plotted as the fraction of true positive by total actual positive called the TRUE POSITIVE RATE and true negatives by total actual negatives also called the TRUE NEGATIVE RATE. Values range between 0 and 1.


Saturday, 3 May 2014

Simplifying the map reduce framework

Google MapReduce

What is Map Reduce ?
 Map Reduce is a model to process large amount of data in Parallel.Let user handle Computation aspects and hides the messy details of parallelization, fault tolerance,data distribution and load balancing .

Whats the programming model for MapReduce ?
Input <Key,Value> pair  -> Output <key,Value>pairs.
Map and Reduce two functions.
Map takes input pair,producing intermediate key value pair.
Group all intermediate values assiciated with same intermediate key k and pass it to Reduce funtion.

Reduce function :  Merge these intermediate values producing a smaller set if values.
 

What are some of the examples? 
Word Count. Count all occurrence of words in a set of documents. 
Map funciton -> each word plus an associated count..
Reduce function -> sum together all counts emitted.

Distributed Grep :  Map : Emits line if matches specific pattern, 
reduce identity function ,copies data to output.   

Count of URL access frequency : 
Map : Logs of web page request outputs <URL,1>
Reduce : Adds all values for the same URL <URL,total count>

Reverse Web Link Graph : 
Map: outout<target,source>
Link pairs target url found on source.  
Reduce : sums all source URL associated with a target.

Distributed Sort
Machine Learning.

What are the steps invloved in Map Reduce ?
1.Split the input file into M pieces of 16 MB or 64 MB.Starts many copies on cluster machine.
2.Follows master and slave model.1 Master many slaves or workers. Master  asssigns idle workers a task from M map and R reduce tasks.
3.Map worker reads input split . generate key value pair form it,pass it to Map function.
4.Map produces intermediate <Key,Value>pair which are buffered in memory.
5. Buffered pairs written to local disk periodically.Local disk partioned into R regions by partitioning function.
6.Location of these passed passed bak to master who forward these to workers.
7.Worker when recieves notification of a location, uses RPC to read buffered data from buffered Disk. Sort the data by intermediate key for grouping.
8.Reduce worker , iterates over sorted intermediate key and for each unique key it passes the <key,Value> pair to reduce function.
9.Writes the output to files.
 
Master :
Stores state(Idle,in-progress or compleated) and identity of worker machine.


Why Combiner Function ?
A mapper function(WOrdCount) produces output in the form <'the',1> with word and its count.  This output is then sent over the network to a single reduce task and clubbed together to produce as many output files as the number of reducer function.
Combiner function does parital merging of data ,before it is sent over the network. Combiner function runs on each machine that has Mapper funciton.
Combiner function significantly speeds up the MapReduce operation by minimizing the number of <k,v> pair that will be sent over the network therby improving the bandwidth. Combiner code is similar to Reducer. 

Saturday, 19 April 2014

Extracting Movie Information from IMDB

A Python Script to access Movie information from IMDB..
you can look at the script on my GIT repository.
GIT 
Goal : To extract Movie Information from IMDB.
Process : 
1) For data scrapping best python Library is Beautiful Soup.
2)Since I use Python3 Mechanize is not available so the work is a little difficult.
3)UrlLib2 module not found error resolved by  this code :
try:
    import urllib.request as urllib2
except:
    import urllib2


4)BeautifulSoup extracts information from the HTML code.
5)Search for a perticular title on IMDB.
6) Most of the time the first result is the one we are searching for .
7)Use Web Scrapping to extratct Movie Information.
8)Rating,Starcast,Critic Raiting and all the information is extracted.

rating = soup1.findAll('span',{'itemprop':'ratingValue'})[0].string

extracts rating from IMDB file . Here itemprop is a Defined class and You are extracting the first element of the itemprop class with name "rating Value"
Beautiful soup API useful for Scrapping
string  : returns the value.
text : returns the text associated with h1..h4, div tags.
other useful ways extract link using 

mainlink=soup.findAll('td',{'class':'result_text'})[0].a['href']


Wednesday, 26 March 2014

Python and NLP

I recently worked on a project titled "Recommending Similar defects on Apache Hadoop" .Its a recommendation system that predicts similar defects and then predicts the effort estimate for each defect.
Steps:
1) Extract XML/Excel data from Apache Hadoop Issue Tracker.
https://issues.apache.org/jira/browse/HADOOP
2)Convert the extracted data into CSV for persistent storage.
3)Extract required Column


Python COde :

import csv
import re

def col_selector(table, column_key):
    return [row[column_key] for row in table]

with open("Data/next.csv","r") as csvfile:
    reader = csv.DictReader(csvfile, delimiter=",")
    table = [row for row in reader]
    foo_col = col_selector(table, "Summary")
    bar_col = col_selector(table, "Description")

The above example extract two columns from Apache Hadoop Issue Tracker CSV file.  Your program must include python library called csv.py
http://docs.python.org/2/library/csv.html

4)From these Column we will generate a set of words specific to Hadoop.
We will apply various NLP to generate various words from the summary and description.

5)There are 5 Steps in Natural Language Processing 
1. Tokenizing
2. Stemming
3. Stop Word Removal
4. Vector Space Representation
5. Similarity Measures

Step 1 : Tokenizing :
 The tokenization process involves breaking a stream of characters of text up into words or phrases, symbols or other meaningful elements called tokens. Before indexing, we Fillter out all common English stopwords.I obtained a list of around 800 stopwords online. 
K. Bounge. Stop Word List.
https://sites.google.com/site/kevinbouge/stopwords-lists
The list contained articles, pronouns, verbs etc. I filtered out all those words from our extracted text. After reviewing the list, we felt stopwords list for a Hadoop Database has to be built separately, as numbers and sym-
bols are also to be filtered out. 


Step 2:
Stemming is used to try to identify a ground form for each word in the text. Some words that carry the same information can be used in different grammatical ways, depending on how the creator of the report wrote it down. This phase will remove a xes and other components from each token
that resulted from tokenization so that only the stem of each word remains. For stemming, we used a python library called PortorStemmer. We passed to it stream of extracted words. Words like caller, called, calling whose stem was call were Filtered and only 1 word, call, was kept in the nal list.I Filtered around 1200 words this way.


Step 3:
Stop Word Removal 
Synonyms removal and replace by 1 common word.I used wordnet NLTK to perform this.
Second Phase : Spell checking: List compared with list of misspelled words.

Step 4:
Vector Space representation.
After the first 3 steps I had around 5500 words. These words were used to identify tags.Each defect with tags was then represented into a Vector space model.Used general method used by scikit.

Step 4: Similarity Measure.
Calculated the cosine similarity between the two defect vectors.