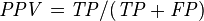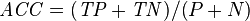Showing posts with label Data Mining. Show all posts

Wednesday, 24 June 2015

Playing with Tumblr API

1. Install Ouath2
2. Install Pytumblr
3. Register an Application
https://www.tumblr.com/oauth/apps
4. Get tumblr ouath2, you will get once you create app

5. Enter your credentials in following code in Python file
client = pytumblr.TumblrRestClient(
    '<consumer_key>',
    '<consumer_secret>',
    '<oauth_token>',
    '<oauth_secret>',
)
pytumblr is a library,  through which you can make calls to tumblr.

6. Code to get all blogs you are following
off =0
while True:
    my_dict = client.following(offset =off)
    res = my_dict['blogs']
    for rs in res:
        print(rs['name'] + "...." + rs['title'])
   
       
    off+=20
7. Number of posts liked for each blog
off =0
like_dict= {}
while True:
    my_dict = client.blog_likes('conflatedthought.tumblr.com',offset =off)
    res = my_dict['liked_posts']
    for rs in res:
        strs = str(rs['tags']).strip('[]')
        #print(rs['blog_name'] +" "+ strs)
        #print("..")
        if rs['blog_name'] in like_dict.keys():
            like_dict[rs['blog_name']] += 1
            #print rs['blog_name'] +"  " + str(like_dict[rs['blog_name']])
        else:
            like_dict[rs['blog_name']] = 1   
          
    off+=20
for the_key, the_value in like_dict.iteritems():
    print the_key, 'corresponds to', the_value 
8. Sample Output for code 6
sportspage....Sports Page
themobilemovement....The Mobile Movement
adidasfootball....adidas Football
instagram-engineering....Instagram Engineering
soccerdotcom....SOCCER.COM
sony....Sony on Tumblr
yahoolabs....Yahoo Labs
taylorswift....Taylor Swift
beyonce....Beyoncé | I Am
itscalledfutbol....Did someone say "futbol"?
futbolarte....Futbol Arte
fcyahoo....FC Yahoo
yahooscreen....Yahoo Screen
yahoo....Yahoo
engineering....Tumblr Engineering
yahoodevelopers....Yahoo Developer Network
mongodb....The MongoDB Community Blog
yahooeng....Yahoo Engineering
marissamayr....Marissa's Tumblr
staff....Tumblr Staff

whoagurt....Whoagurt
narendra-modi....Narendra Modi
nytvideo....New York Times Video
bonjovi-is-my-life....Bon Jovi♥ Is My Life
etsy....Etsy
game-of-thrones....You win or you die.
seinfeld....Seinfeld
itunes....iTunes
teamindiacricket....Team India
gameofthrones....Game of Thrones: Cast A Large Shadow
forzaibra....Forza Ibra

Saturday, 4 October 2014

Data Analysis Yahoo Finance Data

What the Script does :
=> Downloads historical Stock Prices for a company from Yahoo Finance website.
=> Calculates the 10 day moving average.
=> Generate the graph for the data


a) Necessary Imports:
1. Import Panda. Panda is a data analysis library of python.  Pandas has tool to read and write between in-memory data structures and different file formats. It has efficient data frame object for data manipulation with better indexing support.
2. Import Datetime: Provides classes to manipulate date and time objects. Api to convert between different file formats.
3. Import matplotlib: Python 2D plotting library , simple to use and genrates graphs, plots etc with few lines of code. 
4. Import Numpy : Scientific computing package for python,N-Dimensional array object ,Linear algebra related functions.
5. Import urlib: URL handling module for python
import pandas as pd
import pandas.io.data
from datetime import timedelta
import datetime as dt
from pandas import Series, DataFrame
import matplotlib.pyplot as plt
import matplotlib as mpl
import urllib.request
import numpy as numpy
from datetime import datetime
from matplotlib.pyplot import *
import matplotlib.dates as mdates

b) Create a class called Stock 
The main(Init) function should accept as parameter the company symbol, lookback period, window size,and the end date.
def __init__(self,symbol,lookback_period,window_size,end=datetime.date.today()): 
Suppose your lookback period is 100 then get prices for 100 days.
SO to get prices for 100 days subtract from the end date the lookback period.
But for that you need to use same format . 
In this example I have used timedelta.  Time delta helps you get the start date by specifying the number of days  from given date. Like your end date is today and you want stoc prices for last 100 days ,we can use timedelta.

start = end - timedelta(days=lookback_period)
c) Convert date into required format.
start_date = start.isoformat() 
d)  get the required Url for data analysis. 
url = "http://ichart.finance.yahoo.com/table.csv?s={0}".format(symbol)
url += "&a={0}&b={1}&c={2}".format(start_month,start_day,start_year)
url += "&d={0}&e={1}&f={2}".format(end_month,end_day,end_year)
e) Parse data
df = pd.read_csv(urllib.request.urlopen(url))
#get the adj close from csv
saved_column = df['Adj Close']
#get the matching date
y_data = df['Date']
f) Get the moving average
def movingaverage(self,interval, window_size):
window = numpy.ones(int(window_size))/float(window_size)
return numpy.convolve(interval, window, 'same')

Moving Average smooths price fluctuations by removing the noise. It computes the averages of a subset of full data set.

Moving Average Wiki 

g) Generate the graph
 x_data = x_points[0:70]
#get the moving average
y_av = self.movingaverage(saved_column,window_size)
#generate graph
figure("Plot of stocks")
x = [dt.datetime.strptime(d,"%Y-%m-%d").date() for d in x_data]
gca().xaxis.set_major_formatter(mdates.DateFormatter("%Y-%m-%d"))
gca().xaxis.set_major_locator(mdates.DayLocator())
plot(x,y_av,'r')
plot(x,close,'g')
gcf().autofmt_xdate()
xlabel("Date")
ylabel("adjusted close")
show()

GIT

Thursday, 29 May 2014

Understanding Evaluation Metrices.


Confusion Matrix is a tabular layout that can be used to measure the performance of an algorithm. Each Column represents predicted value and each row represents actual value. 
Lets take an example of testing a person for cancer. 
If the person has cancer , the test will say it as positive and if not then negative.
There are can be 4 outcomes if we consider test as an experiment.

1) The patients were suffering from cancer and our test recognized them as suffering from Cancer : These are called TRUE POSITIVE.
2) The patients were suffering from cancer but tests showed negative : These are called TRUE NEGATIVE
3) Patients who were healthy but were diagnosed as suffering from Cancer : FALSE POSITIVE
4) Patients who were not suffering from cancer and test said the same : FALSE NEGATIVE.

Precision (Positive Predicted Value) : proportion of patients test showed as having cancer and they actually had cancer.

\mathit{PPV} = \mathit{TP} / (\mathit{TP} + \mathit{FP})
  
Recall(True Positive Rate)  : proportion of patients that actually had Cancer were diagnosed by test as having cancer. :
\mathit{TPR} = \mathit{TP} / P = \mathit{TP} / (\mathit{TP}+\mathit{FN})
 
Precision and Recall Inversely Related

Accuracy : 
Ratio of Correctly classified instances to total instances.
In layman terms : Number of times the test were right 
\mathit{ACC} = (\mathit{TP} + \mathit{TN}) / (P + N)

Where P and N are total number of tests.


F1 :  is a measure that combines the precision and recall rates by computing the harmonic mean between them. F-Measure does not consider True Negatives into account. 

\mathit{F1} = 2 \mathit{TP} / (2 \mathit{TP} + \mathit{FP} + \mathit{FN})


ROC Curve
Receiver Operating Curve(ROC)  is a plot to show change in performance of Binary Classifier with change in Threshold. The graphs are plotted as the fraction of true positive by total actual positive called the TRUE POSITIVE RATE and true negatives by total actual negatives also called the TRUE NEGATIVE RATE. Values range between 0 and 1.


Saturday, 19 April 2014

Extracting Movie Information from IMDB

A Python Script to access Movie information from IMDB..
you can look at the script on my GIT repository.
GIT 
Goal : To extract Movie Information from IMDB.
Process : 
1) For data scrapping best python Library is Beautiful Soup.
2)Since I use Python3 Mechanize is not available so the work is a little difficult.
3)UrlLib2 module not found error resolved by  this code :
try:
    import urllib.request as urllib2
except:
    import urllib2


4)BeautifulSoup extracts information from the HTML code.
5)Search for a perticular title on IMDB.
6) Most of the time the first result is the one we are searching for .
7)Use Web Scrapping to extratct Movie Information.
8)Rating,Starcast,Critic Raiting and all the information is extracted.

rating = soup1.findAll('span',{'itemprop':'ratingValue'})[0].string

extracts rating from IMDB file . Here itemprop is a Defined class and You are extracting the first element of the itemprop class with name "rating Value"
Beautiful soup API useful for Scrapping
string  : returns the value.
text : returns the text associated with h1..h4, div tags.
other useful ways extract link using 

mainlink=soup.findAll('td',{'class':'result_text'})[0].a['href']